Agents that sleep: freezing and thawing a digital employee in milliseconds会睡觉的智能体:毫秒级冻结与解冻
Most agents spend most of the day waiting. AIDC Cloud freezes an idle agent after a minute and thaws it in 10 to 33 milliseconds when work arrives.大多数智能体一天里的大部分时间都在等。AIDC Cloud 让闲置一分钟的智能体冻结,活来了 10–33 毫秒解冻。
October 7, 2026 · 4 min read2026 年 10 月 7 日 · 阅读约 3 分钟
A digital employee in a busy team might take a few dozen requests a day. A lookup at nine, a draft at eleven, a summary on Friday afternoon. Between those moments, it waits.
If you run that agent the way you run a web server, you pay for the waiting: a process that holds CPU and memory around the clock for work that takes minutes. Multiply by one agent per department, and then by one agent per role, and the cost of idle time quickly becomes the cost of the whole system.
AIDC Cloud is built around a different assumption: an agent should be cheap to keep and instant to wake. This post explains how it works.
The shape of agent work
Agent work has three properties that a runtime has to respect.
It is bursty. Requests arrive in clusters, around meetings, deadlines and shift changes, with long quiet stretches in between.
It is stateful. An agent carries sessions, memory, skills and working files. Throwing that away between requests and rebuilding it on the next one is slow and loses context.
It is conversational. When someone writes to an agent in a chat, they expect the first words back in about the time it takes a colleague to start typing.
A runtime that is always on handles the third property and fails the first. A runtime that starts from scratch on every request handles the first and fails the other two. We wanted all three.
One agent, one runtime environment
Every agent on AIDC Cloud gets a runtime environment of its own: its own process group, running as its own Linux user, with its own home directory. Sessions, memory, skills and workspace files live in that directory, and can be snapshotted per agent into the customer's own storage bucket, versioned and encrypted.
Keeping each agent's state on its own disk is what makes the next step possible. The process can stop doing anything without the agent forgetting anything.
Freeze when idle, thaw on work
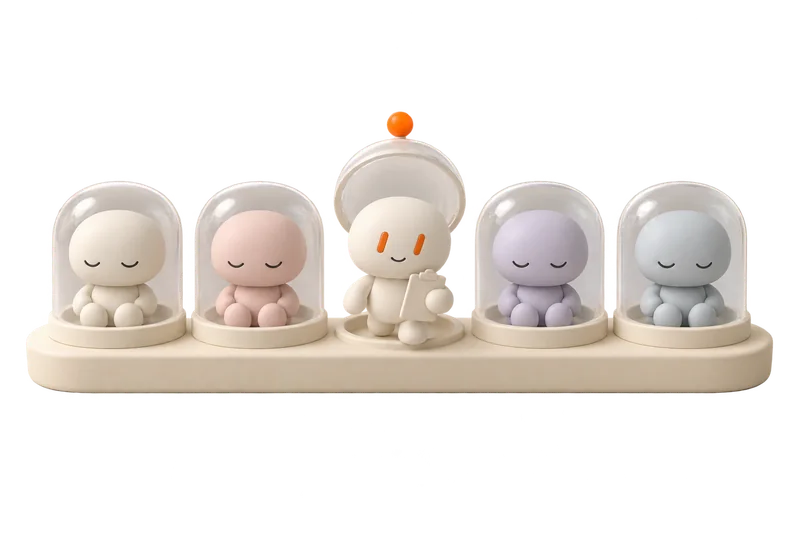
After 60 seconds without work, the agent's processes are frozen. They stop using CPU, and their memory is compressed in place, to about 60 to 70 MB per agent.
When work arrives, the agent thaws. In production we measure the thaw at 10 to 33 milliseconds, and the agent is ready to work in about a second; the first words of an answer follow in about two. Agents in regular use are pre-warmed, so they skip the cold start entirely.
Two numbers are worth separating, because they are easy to blur. The thaw itself takes milliseconds. Being ready to answer takes about a second, because the agent still has to read the new message and decide what to do. Both are fast enough that, in a chat, the person on the other side does not notice the agent was asleep.
Someone has to hold the line
A chat channel expects a live connection. If the connection lived inside the agent, the agent could never sleep.
So the connection lives somewhere else. A small, always-on receiver holds the chat connections for the agents behind it, and when a message arrives it hands the work to the dispatcher, which wakes the right agent. The receiver is the only part that never sleeps, and it is deliberately tiny.
For channels a company connects itself, the agent is called through an OpenAI-compatible endpoint: the company's own code receives the message, calls the agent, and the agent wakes, answers and goes back to sleep.
One task at a time, under a lease
Dispatching work to sleeping agents raises an obvious question: what if two messages arrive at once, or the machine running an agent disappears halfway through a task?
The dispatcher gives each agent one task at a time, and each task runs under a lease. If a node drops out, the lease expires and the task is dispatched again. An agent never works on two things at once in a way that corrupts its own state, and work is not silently lost when hardware fails.
Agents should be cheap to keep and instant to wake. Everything else in the runtime follows from that sentence.
What this changes
The unit of cost becomes the work rather than the uptime. A frozen agent still occupies its compressed memory and its disk, so idle is cheap rather than free, but it no longer holds a CPU waiting for a message.
That changes what a company can afford to deploy. Instead of rationing agents to a few high-traffic jobs, it can give every department, and later every role, an agent of its own, each with its own memory and files, and pay for the work they actually do.
The scope, precisely
Isolation on AIDC Cloud is at the level of operating-system users and process groups. It is designed for a company's own agents doing the company's own work, not for running untrusted code from strangers. We say this plainly because runtime claims are easy to inflate, and the people choosing a runtime deserve the exact boundary.
Within that boundary, the design does what we needed: agents that remember everything, sleep almost all the time and answer as if they never had.
一个忙碌团队的数字员工,一天可能接几十件事:九点查个数,十一点起草一份东西,周五下午出周报。在这些时刻之间,它在等。
如果像运行网站服务器那样运行它,你就在为「等」付钱:一个进程全天占着 CPU 和内存,只为几分钟的活。每个部门一个智能体,再到每个岗位一个,闲置时间的成本很快就成了整个系统的成本。
AIDC Cloud 建立在另一个假设上:智能体应该留着便宜,叫醒很快。这篇讲它怎么做到。
智能体工作的形状
智能体的工作有三个特点,运行时必须照顾到。
它是突发的。请求成簇地来——开会前后、截止日、交接班——中间是长时间的安静。
它是有状态的。智能体带着会话、记忆、技能和工作文件。每次请求之间把这些丢掉、下次再重建,既慢又丢上下文。
它是对话式的。有人在群里找智能体,期待的是:大概同事开始打字的那点时间里,第一句话就回来了。
一直开着的运行时照顾得了第三点,照顾不了第一点;每次从零启动的运行时照顾得了第一点,照顾不了另外两点。我们三点都要。
一个智能体,一个运行环境
AIDC Cloud 上的每个智能体都有自己的运行环境:自己的进程组,以自己的 Linux 用户运行,有自己的主目录。会话、记忆、技能和工作文件都在这个目录里,可以按智能体快照到客户自己的存储桶里,带版本、加密。
每个智能体的状态都在自己的盘上,下一步才做得到:进程可以什么都不做,而智能体什么都不忘。
闲时冻结,来活解冻
60 秒没有活,智能体的进程就被冻结。它们不再占用 CPU,内存在原地压缩,每个智能体约 60–70 MB。
活来了,智能体解冻。我们在生产上测得解冻需要 10–33 毫秒,约 1 秒后就能开始干活,约 2 秒出第一句话。经常用的智能体会预热,干脆跳过冷启动。
这里有两个数值得分开说,因为容易混为一谈。解冻本身是毫秒级;准备好回答要 1 秒左右,因为智能体还要读新消息、决定怎么做。两者都足够快,在群里对面的人察觉不到它刚才在睡。
总得有人守着线
聊天渠道要的是一条一直在线的连接。如果连接放在智能体里,智能体就永远睡不了。
所以连接放在别处。一个很小、一直在线的接收器替身后的智能体守着聊天连接;消息一到,它把活交给调度器,由调度器叫醒对应的智能体。接收器是唯一不睡的部分,它被刻意做得很小。
对公司自己接的渠道,智能体通过一个与 OpenAI 兼容的接口被调用:公司自己的程序收到消息,调用智能体;智能体醒来、回答、再睡回去。
一次一件事,带租约
把活派给正在睡的智能体,会引出一个明显的问题:两条消息同时到怎么办?跑智能体的那台机器干到一半没了怎么办?
调度器给每个智能体一次只派一件事,每件事都带一个租约。某个节点掉线,租约到期,这件事就重新派发。智能体不会同时做两件事、把自己的状态弄乱;硬件出故障时,活也不会悄无声息地丢掉。
智能体应该留着便宜,叫醒很快。运行时里的其他一切,都从这句话推出来。
它改变了什么
成本的单位从「开着的时间」变成了「干的活」。冻结的智能体仍然占着压缩后的内存和自己的盘,所以闲置是便宜,不是免费;但它不再为了等一条消息占着一颗 CPU。
这改变了一家公司部署得起什么。不必再把智能体只配给几个高频岗位,可以给每个部门、以后给每个岗位都配一个自己的智能体,各有各的记忆和文件,按它们实际干的活付钱。
边界,说准确
AIDC Cloud 的隔离在操作系统用户和进程组这一层。它为公司自己的智能体做公司自己的事而设计,不是用来跑陌生人的不可信代码的。我们把这一点说清楚,因为运行时的说法很容易被夸大,而选运行时的人应该知道准确的边界。
在这个边界之内,这套设计做到了我们要的:智能体什么都记得,几乎一直在睡,回答起来又像从没睡过。
AIDC · AI Deployment CompanyAIDC · AI Deployment Company